The earnings-call transcript is becoming an API surface
Buy-side agents want speaker-tagged, timestamped, section-delimited feeds. The format layer, not raw accuracy, is where the transcription category will be decided.
For two decades, the earnings-call transcript sat in a fixed shape: a PDF or an HTML block posted to an issuer's investor relations page a day or three after the call, plus a licensed text feed inside Bloomberg, FactSet, S&P Capital IQ, and Refinitiv for the buy-side desks that would pay for it. The document was written for a human research associate who would read it, highlight it, and paste chunks into a memo. That reader is not the marginal reader anymore. The marginal reader is a retrieval pipeline behind a buy-side agent, and it does not want a PDF.
Our read is that this shift, from human-readable document to machine-consumable feed, is the single most consequential structural change in the transcription category since the entry of specialist vendors like Aiera and Quartr a decade ago. And the competitive battleground is moving with it. Word error rate, the metric transcription vendors have marketed on since the deep-learning era began, is becoming table stakes. Schema depth is becoming the moat.
From document to feed
The classical earnings-call transcript is a document. It has a title, a date, a company name at the top, a list of participants, a prepared remarks section, a Q&A section, and a legal disclaimer. It was designed to be read. When a research analyst wanted to model a segment, they scrolled to the CFO's prepared remarks, found the revenue commentary, and typed it into a spreadsheet. The transcript was the substrate; the model was the output; the human was the interface between them.
An agent workflow inverts that stack. The agent is the interface. The model is a prompt template. The transcript has to arrive as a structured object the retrieval layer can chunk sensibly, cite precisely, and route to the right sub-question. A chunk that spans the boundary between a CFO's prepared remarks and an analyst's Q&A question is a chunk that will produce a hallucinated attribution downstream. A chunk that contains a forward-looking guidance sentence with no disclosure tag is a chunk that will get cited without the appropriate caveat. Neither of these problems is solvable at the retrieval layer if the underlying transcript is a wall of text with speaker names inline.
So the format has to change. And it is changing, unevenly, across three layers of the stack: the issuer, the aggregator, and the agent.
What buy-side agents actually consume
The agent layer is the demand signal, so it is worth starting there. Rogo and Hebbia Matrix are the two purpose-built buy-side incumbents; Perplexity's Comet browser has stitched in Guidepoint, Dun & Bradstreet, and IBISWorld connectors for research workflows; and OpenAI's ChatGPT for Financial Services launched with FactSet and S&P Global integrations already wired in. Each of these agents needs the same primitive: a transcript object with resolved speaker identity, a role tag (executive, analyst, operator), a section tag (prepared remarks, Q&A, closing), a ticker, a fiscal period, and ideally per-utterance timestamps that map back to the audio.
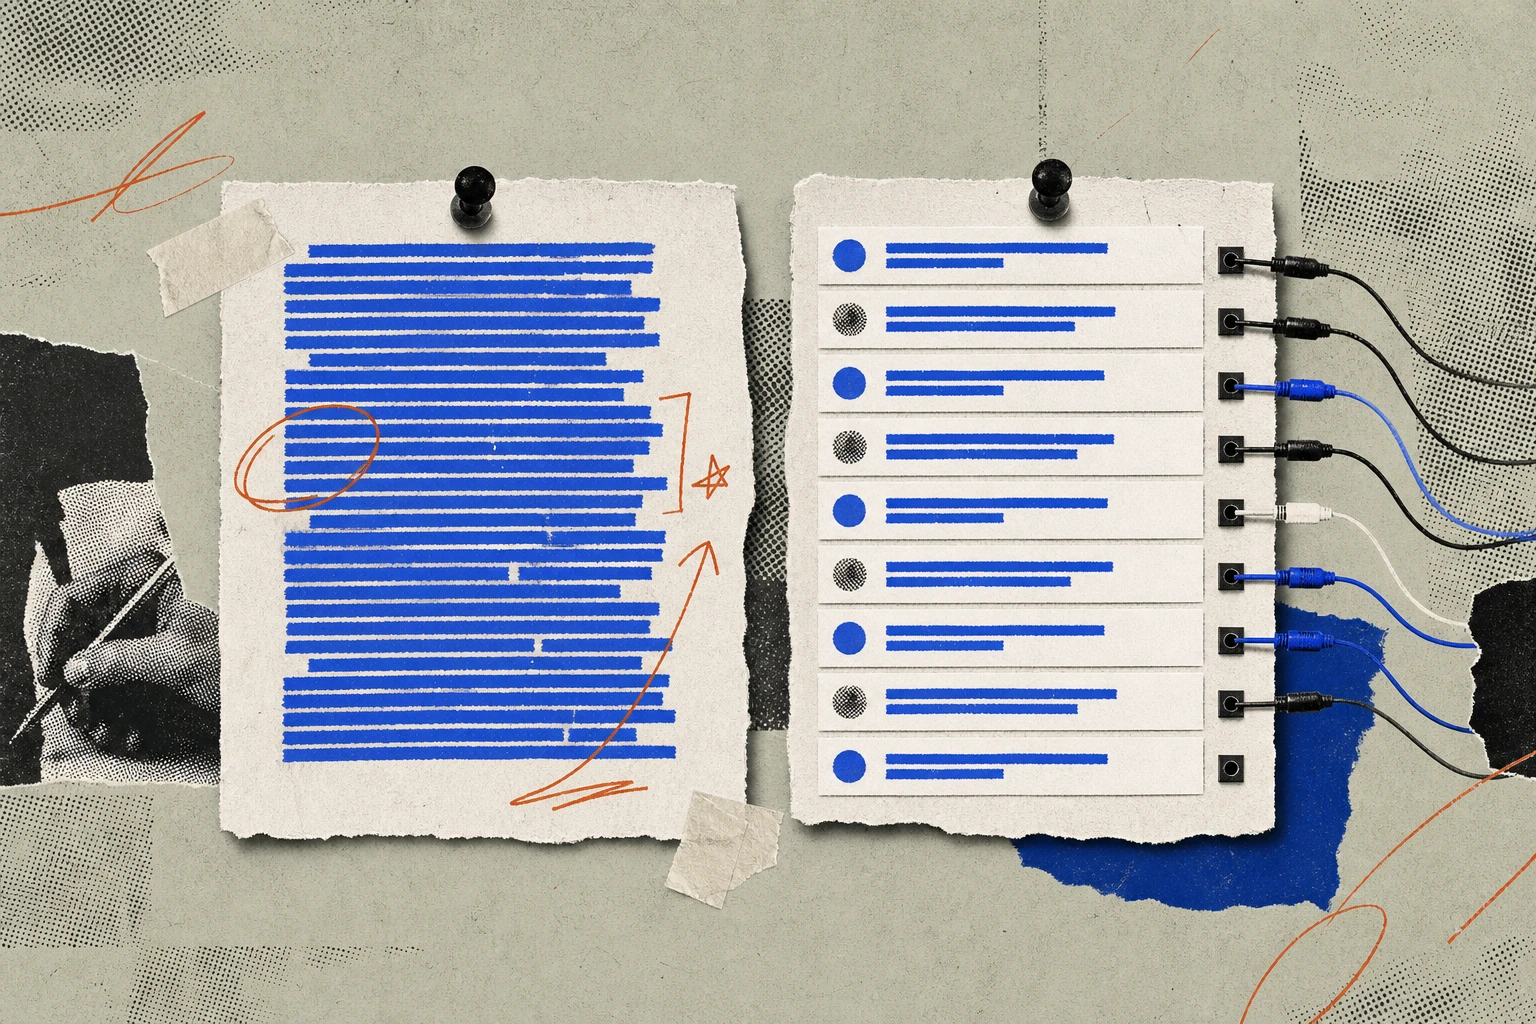
With those fields, an agent can answer a question like "what did the CFO say about gross margin guidance for the next fiscal year on the last three earnings calls" by pulling exactly the CFO's utterances, exactly from the guidance-adjacent sentences, exactly from the right periods, and citing back to timestamped source. Without them, it retrieves paragraph-sized chunks of undifferentiated text, guesses at speaker attribution, and produces a summary the analyst cannot defend to an investment committee.
The gap between those two outcomes is not a model-quality problem. It is a schema problem. The most capable frontier model in the world, given a PDF with speaker names inline and no section markers, will produce the same class of attribution error a smaller model would, because the information the model needs to disambiguate the speaker is not encoded in a form it can reliably parse. This is the argument for treating the transcript as an API surface: the format is the product.
MCP is forcing the schema question
The Model Context Protocol is the immediate accelerant. MCP standardises the handshake between an agent and a data source, which means a transcript vendor that exposes an MCP server no longer has to negotiate a bespoke integration with each agent host. It exposes its resources and tools once, in a typed schema, and any MCP-aware agent can query it.
That sounds like a purely technical convenience. Our view is that its structural effect is larger. Before MCP, the buyer of a transcript feed was an internal data engineering team, and the currency of the sale was fields in a REST or FIX-style API. After MCP, the buyer is effectively the agent, and the currency is the semantic richness of the resources exposed. A transcript vendor that exposes only a get_transcript(ticker, date) tool has done the minimum. A vendor that exposes get_prepared_remarks(ticker, fiscal_period, speaker_role), get_guidance_statements(ticker, fiscal_period), get_analyst_questions(ticker, fiscal_period, firm), and get_disclosure_flagged_utterances(ticker, fiscal_period) has built a schema that meaningfully expands what a downstream agent can do without additional retrieval logic.
The competitive implication is that vendors will be graded on the shape of their schema, not on the length of their coverage list. A vendor that covers every listed issuer in the world but exposes each transcript as a single blob is, from the agent's perspective, less useful than a vendor that covers a narrower universe but exposes the transcript as a graph of typed, queryable resources. This is a real inversion of the historical scorecard, where breadth of coverage was the dominant purchasing criterion.
Where the incumbents sit
The specialist vendors have all read the same weather. Aiera has publicly emphasised real-time structured event feeds as its core positioning, which is the correct posture for an agent-consuming world: the transcript is not a document that arrives once, but a stream of typed events (speaker turn, guidance statement, Q&A question, disclosure flag) that a downstream system can subscribe to. Quartr distributes transcripts with metadata through its API to fintech and research clients, which is the closest thing in the category to a developer-first posture: the transcript is a resource, the metadata is first-class, and the integration model assumes a programmatic consumer.
AlphaSense, through its acquisition of Tegus, sits on the largest combined corpus of expert-call and earnings-call transcripts in the market, and its product marketing centres on structured search across both. The strategic bet there is that the transcript corpus is a single asset class, and the buyer wants one query surface across expert calls, earnings calls, broker research, and filings, with consistent field semantics across all of them. That is a schema play as much as a coverage play.
The legacy terminals , Bloomberg, FactSet, S&P Capital IQ, Refinitiv , are less publicly explicit about the schema question, but their integrations with the agent layer suggest the same direction of travel. FactSet and S&P Global appearing as launch integrations for ChatGPT for Financial Services is not a licensing deal in the old sense. It is a schema commitment: the transcript and filings data those vendors expose has to be shaped in a way an agent can query without a human intermediary.
None of this is happening in a market where the underlying content is scarce. The content is a commodity. The call happens once, at a fixed time, and every credentialed vendor has access to the audio. What is not a commodity is the shape in which the content is delivered downstream. That is where the margin is moving.
The issuer layer is the wild card
The cleanest version of this future is one in which the issuer itself posts a structured, agent-ready transcript to its IR page within an hour of the call, with speaker resolution, section delimiters, and disclosure tags encoded in a standard schema. Some Fortune 500 issuers are close to this today: same-day transcripts, speaker labels, timestamped audio linked from the same page. Many others are not. A material share of the S&P 500, and the vast majority of small-cap issuers globally, still rely on third parties to produce the canonical transcript, which arrives days after the call and lives in a licensed data feed the retail agent user will never see directly.
This inconsistency is the durable business case for the aggregator layer. If every issuer posted a structured transcript to a well-known URL under a common schema, the aggregator's job would collapse to indexing. Because they do not, and because the schema conventions that do exist are informal, the aggregator layer is doing three jobs at once: ingestion and normalisation across inconsistent issuer outputs; enrichment with fields the issuer does not encode (guidance extraction, sentiment, cross-call linkage); and distribution through modern interfaces (REST, GraphQL, MCP) to a downstream consumer that no longer looks like a human.
Our read is that the aggregator layer is safe for the foreseeable future, but its centre of gravity will shift. Ingestion and normalisation will commoditise as issuer practice slowly converges. Enrichment and structured distribution are where the pricing power will concentrate.
A concrete example: guidance extraction
Consider a single field: forward guidance. Every earnings call contains some number of forward-looking statements about the next quarter, the next fiscal year, or a multi-year horizon. Some are quantitative (revenue in the range of X to Y), some are qualitative (we expect gross margin to improve modestly), some are conditional (assuming current FX rates hold), and all of them sit under a legal disclaimer read at the top of the call.
A raw transcript encodes none of this. A structured transcript with a guidance tag on each qualifying utterance encodes the boundary between backward-looking commentary and forward-looking commentary, which is exactly the boundary a buy-side agent needs to respect when producing a summary. A structured transcript with a guidance tag plus a disclosure link encodes the further requirement that any citation of the guidance statement carry the appropriate safe-harbour context.
Building this field reliably is not a WER problem. A transcription engine with a 2% WER and no guidance-tagging schema is less useful, for this specific downstream job, than a transcription engine with a 4% WER and a well-tuned guidance classifier that runs on the transcript post-hoc. The lesson we take from this is that the accuracy conversation has bifurcated. Verbatim accuracy on the underlying words is one problem, and it is close to solved. Semantic accuracy on the structured fields that sit on top of the words is a much harder problem, and it is where the next several years of vendor differentiation will happen.
What this means for term-category accuracy
INFLXD has argued before that a single WER number is the wrong benchmark for transcription vendors serving finance, because the errors that matter are concentrated in narrow term categories , tickers, drug names, product SKUs, executive names, financial metrics. A 1% WER on a transcript that misspells TSMC as DSMC and reads EBITDAX as EBITDA is a transcript that will fail every downstream retrieval query that depends on those tokens.
The schema shift extends this argument. If the transcript is an API surface, the accuracy question is not just "did the vendor transcribe the words correctly" but "did the vendor resolve the speaker, tag the section, classify the utterance, and encode the disclosure context correctly." Each of those is its own accuracy metric, with its own error modes, its own downstream failure surface, and its own claim on the buyer's attention. A serious benchmark for the category, in our view, will publish per-field accuracy across a schema that includes at minimum: speaker resolution, role tagging, section boundary detection, guidance classification, and ticker linkage. A vendor that posts only a WER number is, three years from now, marketing on the wrong dimension.
What buyers should be asking
For a research operations lead, a data engineering team, or a chief technology officer at a buy-side firm, the procurement conversation with a transcript vendor is changing. The old questions were about coverage, latency, and pricing per transcript. The new questions are structural.
The questions we would put to a transcript vendor in 2026, in order:
- What is your published schema for a transcript object, and does it include typed fields for speaker identity, speaker role, section boundary, per-utterance timestamps, ticker, and fiscal period?
- Do you expose an MCP server or an equivalent typed interface, and what resources and tools does it expose beyond
get_transcript? - What is your per-field accuracy on speaker resolution and section boundary detection, measured against a held-out corpus?
- How do you handle guidance classification and disclosure tagging, and are those fields exposed in your API or produced only for internal search?
- What is your latency from end-of-call to structured transcript availability, and what is your latency from end-of-call to first-pass unstructured transcript?
- How do you handle issuer transcripts that are subsequently corrected, and does your feed emit an update event that a subscribed agent can consume?
A vendor that has clean answers to all six is operating in the world the buy-side agent layer is creating. A vendor that only has clean answers to the last two is selling a document, in a market that is buying a feed.
Are your experts using AI to cheat?
Try our free demo to find out today.
Powering institutional-grade transcription for expert networks.
INFLXD provides AI-powered, human-edited transcription with sub-1% error rates for the world's leading expert networks and financial research firms.
Visit inflxd.com →Keep reading.
How Expert Networks Pay Experts: 7 Compensation Structures Behind the Consulting Fee
The mechanics that shape who accepts a call, what the buy-side pays per hour, and why survey work looks nothing like a consulting engagement.
How Buy-Side Firms Handle Expert-Network Call Note-Taking: 7 Structural Models
The workflow choice is rarely documented, varies materially by firm type, and shapes everything from IC-memo latency to agent-readiness.
Rogo raises $30M from bank strategic investors led by Barclays
The generative AI platform for investment banks, PE, hedge funds, and asset managers adds a syndicate of financial institution venture arms to its cap table.